<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://renanfranca.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://renanfranca.github.io/" rel="alternate" type="text/html" /><updated>2026-09-07T14:03:40+00:00</updated><id>https://renanfranca.github.io/feed.xml</id><title type="html">Renan Hipster</title><subtitle>I’m a software engineer who finds joy in going deeper, following my curiosity without needing to know where it will lead. I’m also a Seed4J and JHipster Core Team member and a proud dad.</subtitle><author><name>Renan Franca</name></author><entry><title type="html">What Six Codex Runs Taught Me About Tool Design</title><link href="https://renanfranca.github.io/what-six-codex-runs-taught-me-about-tool-design.html" rel="alternate" type="text/html" title="What Six Codex Runs Taught Me About Tool Design" /><published>2026-09-06T19:40:00+00:00</published><updated>2026-09-06T19:40:00+00:00</updated><id>https://renanfranca.github.io/what-six-codex-runs-taught-me-about-tool-design</id><content type="html" xml:base="https://renanfranca.github.io/what-six-codex-runs-taught-me-about-tool-design.html"><![CDATA[<p><img src="https://renanfranca.github.io/img/postbanners/2026-09-06-cover-what-six-codex-runs-taught-me-about-tool-design.jpg" alt="cover image" /></p>

<h2 id="the-score-was-not-the-most-interesting-result">The score was not the most interesting result</h2>

<p>The String Calculator was never the object of this experiment. It was a small Java kata often used to practice TDD, giving a coding agent a concrete reason to use Seed4J CLI.</p>

<p>The object was the interaction among three parts: the agent interpreting the goal and choosing capabilities, a skill installed in the repository guiding how it should discover, plan and verify, and Seed4J CLI validating and materializing the selected transformations.</p>

<p>In <a href="https://renanfranca.github.io/from-an-empty-repository-to-a-java-kata-one-module-at-a-time.html">From an Empty Repository to a Java Kata, One Module at a Time</a>, I followed that interaction through one complete Codex run, from an empty repository to a Java and Maven foundation and then to the kata implementation.</p>

<p>I had also repeated the same task five more times, changing which model powered Codex or how much reasoning effort it used. All six runs started from the same commit and kata specification, received the same prompt and used Seed4J CLI v0.0.4 with Seed4J 2.2.0. All six produced a working String Calculator implementation, passed the build included in the project and passed the same independent tests covering the kata requirements.</p>

<p>I initially evaluated them with a <a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/blob/main/MODEL_EVALUATION.md">shared rubric</a>. It awarded up to 100 points across Seed4J effectiveness, required behavior, tests and design. The rubric was useful for comparing the runs against the same criteria, but it reduced each execution to a score.</p>

<p>Comparing the commands and messages recorded during the six runs did not change the subject of the experiment. It made the different paths through the same interaction visible.</p>

<p>One run showed the workflow in action. Six runs showed how differently agents navigated that workflow.</p>

<h2 id="what-i-mean-by-a-decision-trajectory">What I mean by a decision trajectory</h2>

<p>I am not trying to infer the model’s private reasoning. The recorded commands and messages do not expose it, and I do not need it for this comparison.</p>

<p>There is already a lot I can observe:</p>

<ul>
  <li>which commands a run executes before changing the repository;</li>
  <li>which modules it inspects as candidates;</li>
  <li>which inspected modules it leaves out;</li>
  <li>whether it creates one complete plan or several smaller plans;</li>
  <li>how tool or environment feedback changes the next action;</li>
  <li>which capabilities it delegates to Seed4J;</li>
  <li>what it verifies after generation.</li>
</ul>

<p>I think of that visible sequence as a decision trajectory.</p>

<p>The six runs used three models: Sol, Terra and Luna. Four used Sol at <code>low</code>, <code>medium</code>, <code>high</code> and <code>xhigh</code> reasoning effort; the other two used Terra and Luna at <code>xhigh</code>.</p>

<h2 id="three-paths-through-the-same-cli">Three paths through the same CLI</h2>

<p>The three <code>xhigh</code> runs provide the cleanest narrative comparison because the reasoning effort stays fixed while the selected model changes.</p>

<p>In the detailed evaluation, Sol <code>xhigh</code> scored 98/100, Luna <code>xhigh</code> 95/100 and Terra <code>xhigh</code> 91/100. All three earned the full 30 points for the required String Calculator behavior. Their remaining differences came from Seed4J usage, tests and design.</p>

<p>The behavior scores confirm a common functional baseline. They do not describe the different paths each run took through the interaction among agent, skill and CLI.</p>

<h3 id="sol-xhigh-anticipated-the-foundation">Sol xhigh anticipated the foundation</h3>

<p>The Sol <code>xhigh</code> run inspected <code>init</code>, <code>maven-java</code>, <code>maven-wrapper</code> and <code>jacoco-with-min-coverage-check</code>, then placed all four modules into one <code>apply-set</code> plan.</p>

<p>Its visible trajectory looked roughly like this:</p>

<pre><code class="language-text">goal → candidate capabilities → one composition → plan → execution
</code></pre>

<p>This run anticipated that the project should have its own Maven launcher and an enforced coverage gate before attempting the kata implementation.</p>

<p>It also exposed an important division of responsibility. The run requested the modules in this order:</p>

<pre><code class="language-text">init
maven-java
maven-wrapper
jacoco-with-min-coverage-check
</code></pre>

<p>Seed4J executed them in this order:</p>

<pre><code class="language-text">init
maven-java
jacoco-with-min-coverage-check
maven-wrapper
</code></pre>

<p>The run chose the capabilities. Seed4J validated the composition and resolved how to materialize it.</p>

<h3 id="terra-xhigh-adapted-to-feedback">Terra xhigh adapted to feedback</h3>

<p>The Terra <code>xhigh</code> run began with a smaller composition: <code>init</code> and <code>maven-java</code>. It planned those modules, applied them and inspected the generated project.</p>

<p>Then it tried to use the global Maven command. The environment returned <code>mvn: command not found</code>.</p>

<p>The next visible message said:</p>

<blockquote>
  <p>The environment has Java 25, but does not have <code>mvn</code>.</p>
</blockquote>

<p>That sentence is my English translation of the original Brazilian Portuguese message in the <a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/blob/9001fe863565408ac3c9622b3b9e7e3edb7786f6/CONVERSATION_TRANSCRIPT.md">Terra run record</a>.</p>

<p>The run then inspected <code>maven-wrapper</code>, generated an individual plan, applied the module and continued through <code>./mvnw</code>.</p>

<p>Its trajectory was different:</p>

<pre><code class="language-text">initial composition → environment feedback → new capability → plan → execution
</code></pre>

<p>Calling this merely a mistake would hide the useful part. In this run, a missing environmental capability produced feedback, and that feedback changed the composition. The final project still recorded the wrapper through the same Seed4J history and commit mechanism.</p>

<h3 id="luna-xhigh-explored-and-kept-the-scaffold-small">Luna xhigh explored and kept the scaffold small</h3>

<p>The Luna <code>xhigh</code> run inspected a broader group of candidates. In addition to <code>init</code>, <code>maven-java</code> and <code>apply-set</code>, it inspected <code>java-base</code> and <code>spring-boot</code>.</p>

<p>After that exploration, its visible message stated that the specification required incremental TDD in Java but did not require a framework or application structure. The run chose a minimal Maven project with JUnit 5 and left <code>java-base</code> and <code>spring-boot</code> out of the composition.</p>

<p>It later inspected <code>maven-wrapper</code> and planned the final set:</p>

<pre><code class="language-text">candidate exploration → minimal boundary → composition → plan → execution
</code></pre>

<p>This is not evidence that Luna generally explores more or that it is inherently more disciplined about scope. It is evidence that this particular run inspected two plausible capabilities and did not apply them.</p>

<h2 id="the-other-runs-left-signals-too">The other runs left signals too</h2>

<p>The remaining Sol runs reinforce the point that a score or final file tree does not describe the complete interaction.</p>

<table>
  <thead>
    <tr>
      <th>Run</th>
      <th>Candidate signal</th>
      <th>Initial applied set</th>
      <th>Later change</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Sol low</td>
      <td>Inspected <code>jqwik</code>, but did not select it</td>
      <td><code>init</code>, <code>maven-java</code>, <code>maven-wrapper</code></td>
      <td>None</td>
    </tr>
    <tr>
      <td>Sol medium</td>
      <td>Inspected <code>checkstyle</code>, but did not select it</td>
      <td><code>init</code>, <code>maven-java</code>, JaCoCo gate, wrapper</td>
      <td>None</td>
    </tr>
    <tr>
      <td>Sol high</td>
      <td>Inspected the four modules it selected</td>
      <td><code>init</code>, <code>maven-java</code>, JaCoCo gate, wrapper</td>
      <td>None</td>
    </tr>
    <tr>
      <td>Sol xhigh</td>
      <td>Inspected the four modules it selected</td>
      <td><code>init</code>, <code>maven-java</code>, wrapper, JaCoCo gate</td>
      <td>Seed4J changed the effective peer order</td>
    </tr>
    <tr>
      <td>Terra xhigh</td>
      <td>Did not inspect the wrapper before the initial application</td>
      <td><code>init</code>, <code>maven-java</code></td>
      <td>Added the wrapper after global Maven was unavailable</td>
    </tr>
    <tr>
      <td>Luna xhigh</td>
      <td>Inspected <code>java-base</code> and <code>spring-boot</code>, but did not select them</td>
      <td><code>init</code>, <code>maven-java</code>, <code>maven-wrapper</code></td>
      <td>None</td>
    </tr>
  </tbody>
</table>

<p>This table does not rank the trajectories. It gives me a vocabulary for comparing them: discovery breadth, candidate rejection, planning granularity, proactive composition, reaction to feedback and delegation to the tool.</p>

<h2 id="the-skill-constrained-the-protocol-not-every-decision">The skill constrained the protocol, not every decision</h2>

<p>All six runs had the same <a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/blob/38ebbcbfab95f5725b1c22b1d4701fb6222cab6b/.agents/skills/seed4j-cli/SKILL.md">Seed4J CLI skill installed in the repository</a>.</p>

<p>The skill defines an operating protocol:</p>

<ol>
  <li>discover the CLI, runtime and catalog;</li>
  <li>infer candidate modules from the task;</li>
  <li>inspect the active help for those modules;</li>
  <li>plan before mutation;</li>
  <li>execute the validated composition;</li>
  <li>verify the generated result and Git state.</li>
</ol>

<p>That protocol explains part of the consistency across the runs. Every one of them discovered the runtime and catalog. Every one produced a plan before applying modules. Every successful module left history and a commit.</p>

<p>But the skill did not prescribe the exact module set for the kata. It did not say that JaCoCo was mandatory. It did not tell the run whether to inspect Spring Boot, when to add the Maven Wrapper or whether to construct one large plan.</p>

<p>That left a meaningful decision surface for each run:</p>

<ul>
  <li>the run selected the capabilities it wanted;</li>
  <li>the skill guided how to interact with the tool safely;</li>
  <li>Seed4J validated dependencies and parameters, calculated execution order, changed files, updated module history and created commits.</li>
</ul>

<p>This separation is more interesting to me than trying to put every correct decision into the skill.</p>

<h2 id="the-tool-reduced-the-space-of-decisions-that-had-to-be-right">The tool reduced the space of decisions that had to be right</h2>

<p>Without a project generator, a coding run building the same foundation might need to choose Maven plugin versions, write the POM, create the wrapper, configure JaCoCo, place files correctly, preserve project history and decide how to divide infrastructure changes into commits.</p>

<p>With Seed4J, the request can be closer to a set of capabilities:</p>

<pre><code class="language-text">Java with Maven
Maven Wrapper
coverage gate
</code></pre>

<p>The tool then turns that explicit intent into deterministic transformations.</p>

<p>This does not make module selection irrelevant. A run can still omit a useful capability, add one the task does not need or choose parameters poorly. Seed4J also cannot guarantee that the kata implementation itself will be well designed.</p>

<p>What it can do is narrow the area in which those choices operate. Once a valid capability is selected, the run does not also need to reproduce all of the configuration details behind it from memory.</p>

<p>The models can take different routes through discovery and planning without every difference becoming a different manually written build configuration.</p>

<h2 id="this-connects-to-how-i-think-about-skills-and-loops">This connects to how I think about skills and loops</h2>

<p>In <a href="https://renanfranca.github.io/when-skill-evolution-means-removing-instructions.html">When Skill Evolution Means Removing Instructions</a>, I argued that deterministic knowledge should move into deterministic mechanisms whenever possible. A skill can become smaller when a test, hook or tool can enforce what used to depend on an instruction.</p>

<p>In <a href="https://renanfranca.github.io/i-had-already-built-three-agentic-loops.html">I Had Already Built Three Agentic Loops Without Naming Them</a>, I described autonomy becoming safer when feedback and exit conditions live in the environment instead of depending on the model remembering them.</p>

<p>Seed4J gives me another concrete example of both ideas.</p>

<p>The skill does not contain a static catalog or teach the model how to write every generated file. It sends the run to the active CLI. The plan provides feedback before mutation. The runtime validates the composition. The module history and Git commits make the result inspectable afterward.</p>

<p>The model still decides. But it decides inside a workflow with explicit feedback and deterministic boundaries.</p>

<h2 id="what-this-experiment-does-not-show">What this experiment does not show</h2>

<p>This was one kata, one prompt and one run for each model and effort configuration, all executed on the same host. Each run took place in a separate chat, and execution time was not part of the comparison. The records also differ in format and in what they omit, which limits direct comparisons of presentation and completeness.</p>

<p>There was no control group implementing the kata without Seed4J. I therefore cannot claim that Seed4J made the runs faster, cheaper or more correct than another approach.</p>

<p>Most importantly, these trajectories do not establish stable model personalities. I can say that the Terra <code>xhigh</code> run added the wrapper reactively. I cannot conclude from one run that Terra is a reactive model. I can say that the Sol <code>xhigh</code> run anticipated the coverage gate. I cannot conclude that Sol always plans infrastructure better.</p>

<p>The <a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/blob/main/MODEL_EVALUATION.md">detailed experiment report</a> keeps the full protocol, commands, scores and limitations.</p>

<h2 id="a-principle-i-want-to-test-again">A principle I want to test again</h2>

<p>These six runs do not prove a general rule about agent tools. They make one design principle concrete enough for me to keep testing.</p>

<p>Different runs can explore different candidates, compose at different moments and react differently to feedback. A tool does not necessarily need to normalize all of that behavior. It can preserve room for judgment while making dependencies, ordering, parameter resolution, history and mutation more predictable.</p>

<blockquote>
  <p>A good agent tool may not need to eliminate model variability. It may need to constrain where that variability can cause damage.</p>
</blockquote>

<p>If this experiment made you curious about the approach, consider giving <a href="https://github.com/seed4j/seed4j">Seed4J</a> and <a href="https://github.com/seed4j/seed4j-cli">Seed4J CLI</a> a star 🌟 on GitHub. It helps more people discover the projects and follow their evolution.</p>

<h2 id="references">References</h2>

<ul>
  <li><a href="https://seed4j.com/">Seed4J</a></li>
  <li><a href="https://github.com/seed4j/seed4j-cli">Seed4J CLI</a></li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/">Seed4J CLI String Calculator Kata</a></li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/blob/main/MODEL_EVALUATION.md">Detailed experiment report</a></li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/blob/3d179c56b288f0fcbc0c62ee94b5af3152887136/AUDITORIA-CONVERSA.md">Sol xhigh run record</a></li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/blob/9001fe863565408ac3c9622b3b9e7e3edb7786f6/CONVERSATION_TRANSCRIPT.md">Terra xhigh run record</a></li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/blob/7ad4d48b311ff664c2f8e4b012151513cad15916/CONVERSATION_TRANSCRIPT.md">Luna xhigh run record</a></li>
  <li><a href="https://developers.openai.com/api/docs/models">OpenAI model catalog</a></li>
</ul>]]></content><author><name>Renan Franca</name></author><category term="seed4j" /><summary type="html"><![CDATA[How six Codex runs followed different decision paths through the same Seed4J CLI, and why good agent tools may need to constrain variability rather than eliminate it.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://renanfranca.github.io/img/postbanners/2026-09-06-cover-what-six-codex-runs-taught-me-about-tool-design.jpg" /><media:content medium="image" url="https://renanfranca.github.io/img/postbanners/2026-09-06-cover-what-six-codex-runs-taught-me-about-tool-design.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">From an Empty Repository to a Java Kata, One Module at a Time</title><link href="https://renanfranca.github.io/from-an-empty-repository-to-a-java-kata-one-module-at-a-time.html" rel="alternate" type="text/html" title="From an Empty Repository to a Java Kata, One Module at a Time" /><published>2026-09-04T19:28:00+00:00</published><updated>2026-09-04T19:28:00+00:00</updated><id>https://renanfranca.github.io/from-an-empty-repository-to-a-java-kata-one-module-at-a-time</id><content type="html" xml:base="https://renanfranca.github.io/from-an-empty-repository-to-a-java-kata-one-module-at-a-time.html"><![CDATA[<p><img src="https://renanfranca.github.io/img/postbanners/2026-09-04-cover-from-an-empty-repository-to-a-java-kata-one-module-at-a-time.jpg" alt="cover image" /></p>

<h2 id="a-small-project-to-learn-seed4j-cli">A small project to learn Seed4J CLI</h2>

<p>I wanted a small project to learn how to use Seed4J CLI, but with a slightly different constraint: I wanted to learn it the same way I expect to use it in real projects, together with a coding agent.</p>

<p><a href="https://seed4j.com/">Seed4J</a> is a modular code generator. Instead of generating one fixed project, it applies named transformations, called modules, that add or configure one capability at a time.</p>

<p>The Seed4J CLI makes that approach available from the command line.</p>

<p>So I created a repository around the classic String Calculator kata, using the <a href="https://github.com/ardalis/kata-catalog/blob/main/katas/String%20Calculator.md">specification from the Coding Kata Catalog</a>. It is a small testing exercise in which an <code>add</code> function starts with simple string inputs and gradually supports more rules, such as multiple numbers and custom delimiters.</p>

<p>The Seed4J CLI can also install a skill directly in the repository where it will be used. That skill teaches the coding agent how to discover and operate the CLI. The skill guides the agent; the Seed4J modules are what transform the project.</p>

<p>The starting point is intentionally minimal: a specification for the kata and the Seed4J CLI skill installed locally for the agent.</p>

<p>The original prompt was written in Brazilian Portuguese:</p>

<blockquote>
  <p>implement o kata utilizando o seed4j cli tool já instalado como apoio.</p>
</blockquote>

<p>For readability, I translated it to English:</p>

<blockquote>
  <p>Implement the kata with support from the installed Seed4J CLI tool.</p>
</blockquote>

<p>From there, the agent has to inspect the active CLI and decide how to compose the project.</p>

<p>I later repeated the same task across six model and reasoning configurations. Their differences are documented in the detailed experiment report linked below. To keep this post focused, it follows the <code>string-calculator-sol-xhigh</code> run, which used the Sol model with <code>xhigh</code> reasoning effort.</p>

<h2 id="let-the-agent-discover-the-cli">Let the agent discover the CLI</h2>

<p>The agent starts by discovering the command-line client, the Seed4J version behind it, and the modules available to it:</p>

<pre><code>seed4j --version &amp;&amp; seed4j --help
seed4j list
</code></pre>

<p>The command-line client and the Seed4J generator it invokes are versioned separately. This run used Seed4J CLI v0.0.4 with Seed4J 2.2.0.</p>

<p>From the available modules, the agent identifies four capabilities that seem useful and inspects their parameters:</p>

<pre><code>seed4j apply-set --help
seed4j apply init --help
seed4j apply maven-java --help
seed4j apply maven-wrapper --help
seed4j apply jacoco-with-min-coverage-check --help
</code></pre>

<p>The module names describe four separate transformations. Each name below links to the commit Seed4J created for that transformation:</p>

<ul>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/commit/bc2937fbd28b1af9e8d225e3d1aa04e139ce7d88"><code>init</code></a> establishes the common project foundation: project metadata, repository conventions, development tooling, and a record of the Seed4J modules applied. It does not create the Java application.</li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/commit/9c434d1503b32c02415df461182cfb58979c3ccd"><code>maven-java</code></a> adds the Java and Maven build, including the testing dependencies.</li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/commit/675c0a86abae6116bf4aa8c46044164fec19ffec"><code>maven-wrapper</code></a> adds a Maven launcher to the project, so the build does not depend on a separately installed Maven version.</li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/commit/2890bef54b3fb268a447d1e9c62b30084dd3ddfe"><code>jacoco-with-min-coverage-check</code></a> turns code coverage into a build requirement.</li>
</ul>

<p>The <code>apply-set</code> command composes several modules and resolves a valid execution order. Before changing the repository, the agent uses <code>--plan</code> to preview the resolved modules and parameters without applying them:</p>

<pre><code>seed4j apply-set init maven-java maven-wrapper jacoco-with-min-coverage-check --plan --project-path . --project-name 'String Calculator Kata' --base-name stringCalculator --package-name com.renanfranca.stringcalculator --node-package-manager npm --end-of-line lf --indent-size 2
</code></pre>

<p>The plan is valid and Seed4J resolves the execution order as:</p>

<pre><code>init
maven-java
jacoco-with-min-coverage-check
maven-wrapper
</code></pre>

<p>Notice that this is not exactly the order requested by the agent. It placed <code>maven-wrapper</code> before <code>jacoco-with-min-coverage-check</code>. The agent’s order was valid: both modules can be applied after <code>maven-java</code>, and neither depends on the other. Seed4J does not preserve the requested order, however. Because both modules are at the same dependency level, Seed4J 2.2.0 sorts them lexically by slug, placing <code>jacoco-with-min-coverage-check</code> before <code>maven-wrapper</code>.</p>

<p>After reviewing the plan, the agent applies exactly the same composition without <code>--plan</code>.</p>

<p>Seed4J applies the modules sequentially and creates one commit for each successful module.</p>

<p>Once Seed4J finishes, the repository has a common project foundation, a Java 25 Maven build with testing libraries, an enforced coverage threshold, and its own Maven launcher. Seed4J stops at that foundation; it does not generate the String Calculator. From there, the agent <a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/commit/e22bea4e216db808ae7682a63d857f2cce3d8c0b">implements the kata in one production class and one test class</a>. Running <code>./mvnw verify</code> executes 13 behavior tests and enforces 100% line and branch coverage with JaCoCo.</p>

<p>What interested me was not the generated files alone. It was watching the agent discover the available capabilities, select the modules it needed, and let Seed4J resolve and record the composition one module at a time.</p>

<h2 id="the-kata-is-not-the-thing-i-am-trying-to-learn">The kata is not the thing I am trying to learn</h2>

<p>I chose a familiar kata precisely because its implementation was not the variable I wanted to study. It gives me a small, controlled problem where I can watch an AI agent discover Seed4J, choose modules, inspect their parameters, preview the resulting composition, and use those modules to turn an almost empty repository into a Java project.</p>

<p>Instead of asking the agent to manually recreate all the project setup, I can watch it decide which capabilities it needs and let Seed4J apply the corresponding transformations.</p>

<p>The repository records this experiment, including the commands executed by the agents, the modules they selected, the resulting projects, and their Seed4J module history.</p>

<p>What I can observe here is how the agents use Seed4J under this setup. Because every run uses Seed4J, this experiment does not tell me whether Seed4J makes an agent faster, cheaper, or better than another scaffolding approach.</p>

<h2 id="a-small-training-ground">A small training ground</h2>

<p>For me, this makes the kata a small training ground for a larger question: how should I use Seed4J together with AI coding agents in real projects?</p>

<p>I do not think this kata answers that question. It gives me a controlled place to observe the interaction, learn what information the agent needs, and make the next experiment more concrete.</p>

<p>If this experiment made you curious about the approach, consider giving <a href="https://github.com/seed4j/seed4j">Seed4J</a> and <a href="https://github.com/seed4j/seed4j-cli">Seed4J CLI</a> a star 🌟 on GitHub. It helps more people discover the projects and follow their evolution.</p>

<h2 id="reproduction-note">Reproduction note</h2>

<p>Seed4J CLI itself requires Java 25 or newer on your <code>PATH</code>, and its npm launcher requires Node.js 22 or newer. With those prerequisites available, install the CLI and verify the command:</p>

<pre><code>npm install -g seed4j-cli
seed4j --version
</code></pre>

<p>Then, install the optional skill that guides the coding agent by running this command from the kata repository:</p>

<pre><code>seed4j skill install
</code></pre>

<p>I used Codex in the ChatGPT desktop app with Full Access enabled so Seed4J could write to <code>.git</code> and create a separate commit for each module without approval interruptions. In Codex CLI, the equivalent is running <code>codex --yolo</code>. Because that bypasses approvals and sandboxing, it should only be used in a controlled or externally isolated environment.</p>

<h2 id="references">References</h2>

<ul>
  <li><a href="https://seed4j.com/">Seed4J</a></li>
  <li><a href="https://github.com/seed4j/seed4j-cli">Seed4J CLI</a></li>
  <li><a href="https://github.com/ardalis/kata-catalog">Coding Kata Catalog</a></li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/">Seed4J CLI String Calculator Kata</a></li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/tree/string-calculator-sol-xhigh">Sol xhigh implementation</a></li>
  <li><a href="https://github.com/renanfranca/seed4j-cli-string-calculator-kata/blob/main/MODEL_EVALUATION.md">Detailed experiment report</a></li>
  <li><a href="https://learn.chatgpt.com/docs/sandboxing">Codex sandbox and permissions</a></li>
</ul>]]></content><author><name>Renan Franca</name></author><category term="seed4j" /><summary type="html"><![CDATA[Using the String Calculator kata as a small training ground to learn how a coding agent can discover and compose a Java project with Seed4J CLI.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://renanfranca.github.io/img/postbanners/2026-09-04-cover-from-an-empty-repository-to-a-java-kata-one-module-at-a-time.jpg" /><media:content medium="image" url="https://renanfranca.github.io/img/postbanners/2026-09-04-cover-from-an-empty-repository-to-a-java-kata-one-module-at-a-time.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">When Skill Evolution Means Removing Instructions</title><link href="https://renanfranca.github.io/when-skill-evolution-means-removing-instructions.html" rel="alternate" type="text/html" title="When Skill Evolution Means Removing Instructions" /><published>2026-09-02T01:24:00+00:00</published><updated>2026-09-02T01:24:00+00:00</updated><id>https://renanfranca.github.io/when-skill-evolution-means-removing-instructions</id><content type="html" xml:base="https://renanfranca.github.io/when-skill-evolution-means-removing-instructions.html"><![CDATA[<p><img src="https://renanfranca.github.io/img/postbanners/2026-09-01-cover-when-skill-evolution-means-removing-instructions.jpg" alt="cover image" /></p>

<h2 id="two-papers-one-familiar-question">Two papers, one familiar question</h2>

<p>I keep having this strange experience lately: I spend time experimenting with something in a very small, practical way, and then a paper appears exploring a remarkably similar question at a much larger scale.</p>

<p>Two recent papers made that happen again.</p>

<p>The first is <a href="https://arxiv.org/abs/2608.20614">“Evaluating Skills, Not Just Agents”</a>, which introduces ACES and Skill Lift: execute the same task with and without a skill and measure the difference.</p>

<p>That connects directly with what I was exploring in <a href="https://github.com/renanfranca/skill-eval">skill-eval</a>.</p>

<p>But my main takeaway from that experiment was actually about the limits of A/B testing.</p>

<p>An A/B comparison gives evidence for that particular model, task, context and harness. It does not prove that a skill is universally good. Change the model and the skill may become less useful, unnecessary, or even harmful.</p>

<h2 id="knowledge-does-not-have-to-become-instructions">Knowledge does not have to become instructions</h2>

<p>Then I read Google Research’s <a href="https://arxiv.org/abs/2608.27454">“WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution”</a>.</p>

<p>And another piece clicked into place.</p>

<p>WikiSkill separates raw experience, accumulated knowledge and the actual executable skill. Experience can keep accumulating outside the skill, while proposed skill changes are validated before being promoted.</p>

<p>Even more interestingly, the paper shows cases where low-level workarounds learned for one model transfer poorly to a stronger model. Instructions that helped the weaker model could constrain the stronger one or cause redundant tool calls.</p>

<p>That is very close to another experiment I did inside <a href="https://github.com/renanfranca/skill-eval">skill-eval</a>.</p>

<h2 id="evolving-a-skill-by-making-it-smaller">Evolving a skill by making it smaller</h2>

<p>I tried to “evolve” my <code>implement-execplan</code> skill not by adding more instructions, but by removing them.</p>

<p>The original baseline had 228 lines. The adaptive version had 165.</p>

<p>Instead of requiring a large fixed plan structure and continuous updates, the newer version relies more on the model’s own capabilities: fewer mandatory sections, conditional information only when useful, fewer plan updates and less routine bookkeeping.</p>

<p>The skill is here:</p>

<p><a href="https://github.com/renanfranca/codex-skills/blob/main/implement-execplan/SKILL.md">implement-execplan/SKILL.md</a></p>

<p>And the case study is here:</p>

<p><a href="https://github.com/renanfranca/skill-eval/tree/main/docs/case-studies/implement-execplan">skill-eval: implement-execplan case study</a></p>

<p>In the first valid comparison, both versions passed the same quality gates, while the smaller version used about 18% fewer candidate input + output tokens.</p>

<p>That is only one observation, not proof that the new version is universally better. The replication was incomplete, and I deliberately documented that limitation.</p>

<p>But it changed how I think about “skill evolution”.</p>

<p>Evolution does not necessarily mean accumulating more rules.</p>

<p>Sometimes the model improved and part of the harness became obsolete.</p>

<p>Sometimes something that used to require an instruction can become a deterministic test, hook or static check and disappear from the skill entirely.</p>

<p>This is also a continuation of something I noticed while gradually giving TDD to an agent. In <a href="https://renanfranca.github.io/when-i-entrusted-tdd-to-an-ai-agent.html">When I Entrusted TDD to an AI Agent</a>, some architectural guidance became much more reliable once it stopped being only an instruction and became executable feedback in the repository.</p>

<p>And sometimes a failure is worth remembering, but not yet worth turning into an instruction. This is where the WikiSkill separation between experience, persistent knowledge and executable skills makes a lot of sense to me.</p>

<h2 id="i-prefer-to-discover-the-workflow-first">I prefer to discover the workflow first</h2>

<p>This also changed how I create skills.</p>

<p>I prefer to experience the problem first, work with the model manually, adjust the workflow until I can make it work reliably, and only then consolidate what I learned into a skill.</p>

<p>My latest <code>implement-approved-plan</code> skill came from exactly that process:</p>

<p><a href="https://github.com/renanfranca/codex-skills/blob/main/implement-approved-plan/SKILL.md">implement-approved-plan/SKILL.md</a></p>

<p>This one is interesting because the skill itself coordinates a multi-chat workflow inside ChatGPT Desktop.</p>

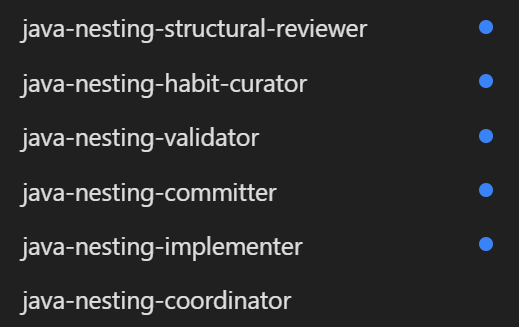
<p>A dedicated Coordinator keeps the approved plan and controls a set of specialized chats. Each role is created once and then reused throughout the implementation: an Implementer works through TDD, a Committer owns commits, a Validator runs the complete quality gates, a Habit Curator handles mechanically detected design findings, and an independent Structural Reviewer looks for design problems after the implementation is already green.</p>

<p>The specialization is not only about giving each chat a different responsibility. The skill also assigns different models to different roles. The Coordinator, Implementer, Habit Curator, and Structural Reviewer run on <code>gpt-5.6-sol</code> at <code>xhigh</code>; the Committer runs on <code>gpt-5.6-terra</code> at <code>xhigh</code>; and the Validator runs on <code>gpt-5.6-luna</code> at <code>xhigh</code>.</p>

<p>That routing makes the workflow more economical. Sol is reserved for open-ended implementation, orchestration, and design judgment; Terra handles commit work, which is narrower but still requires judgment about repository conventions; and Luna runs the mostly deterministic validation gates. The point is not merely to create specialists, but to avoid using the flagship model where a more economical model is sufficient.</p>

<p><img src="https://renanfranca.github.io/img/when-skill-evolution-means-removing-instructions/implement-approved-plan-specific-chats.png" alt="Coordinator and specialist chats created by implement-approved-plan" /></p>
<figcaption>These are the chats created by the <code>implement-approved-plan</code> skill to implement <a href="https://github.com/habit-hooks/habit-hooks/issues/160">habit-hooks issue #160</a> in the amazing habit-hooks project.</figcaption>

<p>Conceptually, it looks roughly like this:</p>

<pre><code class="language-text">Approved Plan
     ↓
Coordinator
     ↓
Implementer
     ↓
Coordinator
     ↓
Committer
     ↓
Coordinator
     ↓
Validator
     ↓
Coordinator
     ↓
Habit Curator
     ↓
Coordinator
     ↓
Structural Reviewer
     ↓
Final Validation
     ↓
PR + CI
     ↓
Ready for Merge
</code></pre>

<p>The interesting part for me is that these chats do not freely coordinate with each other. The Coordinator is the only one talking to the specialists, and access to the same working tree is serialized through a persistent workflow ledger.</p>

<p>That ledger works almost like a small state machine. It records the current phase, specialist chat IDs, commits, validation gates, Habit state, pull request and CI evidence. It rejects invalid transitions, concurrent ownership of the checkout, premature pull requests and cleanup before GitHub actually confirms that the PR was merged.</p>

<p>The shape is more elaborate than the three nested loops I described in <a href="https://renanfranca.github.io/i-had-already-built-three-agentic-loops-without-naming-them.html">I Had Already Built Three Agentic Loops Without Naming Them</a>, but the underlying idea feels similar: autonomy becomes safer when feedback and exit conditions live in the workflow instead of depending on the model remembering everything.</p>

<p>So the skill is not trying to make one giant agent smarter. It is encoding a workflow I had already been performing manually, while moving as much coordination and validation as possible into deterministic machinery around the model.</p>

<p>PR that introduced it:</p>

<p><a href="https://github.com/renanfranca/codex-skills/pull/7">renanfranca/codex-skills#7</a></p>

<p>And instead of stopping when the <code>SKILL.md</code> looked good, I exercised the workflow against a public fixture and a real pull request:</p>

<p><a href="https://github.com/renanfranca/implement-approved-plan-fixture">implement-approved-plan-fixture</a></p>

<p><a href="https://github.com/renanfranca/implement-approved-plan-fixture/pull/2">implement-approved-plan-fixture#2</a></p>

<h2 id="my-current-mental-model">My current mental model</h2>

<p>So my current mental model is becoming something like this:</p>

<p>Experience the problem.</p>

<p>Make the workflow work manually.</p>

<p>Turn deterministic knowledge into deterministic mechanisms.</p>

<p>Keep uncertain experience outside the skill until it earns its place.</p>

<p>Add instructions only for what the model still needs.</p>

<p>And when the model changes, question those instructions again.</p>

<p>No magic skill. No assumption that more instructions mean a better agent.</p>

<p>Just a workflow that keeps adapting as both the model and my understanding of the problem change.</p>]]></content><author><name>Renan Franca</name></author><category term="tales-of-a-dev" /><summary type="html"><![CDATA[What ACES, WikiSkill, skill-eval, and my latest agent workflows taught me about evaluating skills, removing obsolete instructions, and moving knowledge into deterministic mechanisms.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://renanfranca.github.io/img/postbanners/2026-09-01-cover-when-skill-evolution-means-removing-instructions.jpg" /><media:content medium="image" url="https://renanfranca.github.io/img/postbanners/2026-09-01-cover-when-skill-evolution-means-removing-instructions.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">I Had Already Built Three Agentic Loops Without Naming Them</title><link href="https://renanfranca.github.io/i-had-already-built-three-agentic-loops.html" rel="alternate" type="text/html" title="I Had Already Built Three Agentic Loops Without Naming Them" /><published>2026-07-16T15:00:00+00:00</published><updated>2026-07-16T15:00:00+00:00</updated><id>https://renanfranca.github.io/i-had-already-built-three-agentic-loops</id><content type="html" xml:base="https://renanfranca.github.io/i-had-already-built-three-agentic-loops.html"><![CDATA[<p><img src="https://renanfranca.github.io/img/postbanners/2026-07-16-cover-i-had-already-built-three-agentic-loops.jpg" alt="cover image" /></p>

<h2 id="i-was-already-working-with-loops">I was already working with loops</h2>

<p>After reading Laurie Voss’s article <a href="https://www.linkedin.com/pulse/what-hell-loop-anyway-laurie-voss-ldmdc">What the hell is a loop, anyway?</a>, I realized that I had naturally ended up with three layers of loops in my workflow with coding agents.</p>

<p>I had not deliberately designed something I called a loop architecture.</p>

<p>I had been trying to solve practical problems.</p>

<p>How could I give an agent enough autonomy to implement a complete feature without losing the destination?</p>

<p>How could I divide a large implementation into observable units of progress?</p>

<p>How could I ensure that the code evolved through behavior while continuing to respect the architecture?</p>

<p>The solutions I adopted gradually became three nested feedback loops.</p>

<p>I just did not have a name for them.</p>

<h2 id="these-are-loops-inside-one-implementation">These are loops inside one implementation</h2>

<p>My three layers do not map perfectly to the four loop architectures Laurie describes.</p>

<p>I am not running an autonomous software factory that chooses work from a backlog, ships it, monitors production, and starts again.</p>

<p>The loops I see are inside the implementation of a single change.</p>

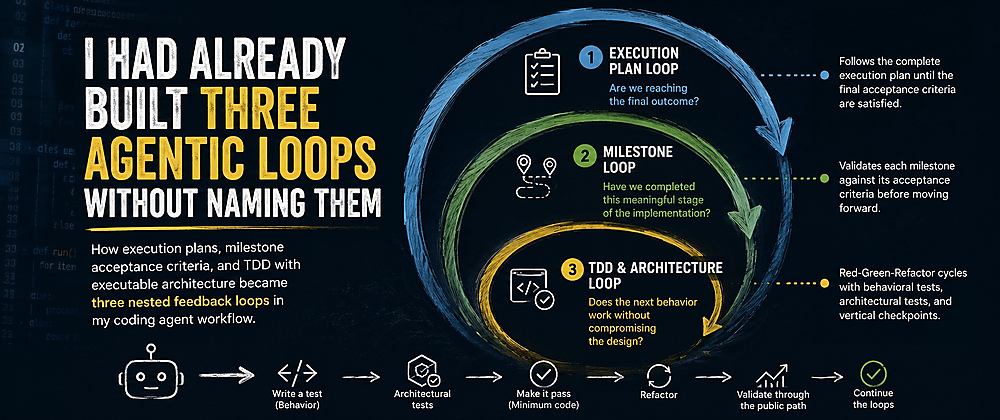
<p>The outer loop follows the complete execution plan.</p>

<p>Inside it, another loop follows the milestones.</p>

<p>Inside each milestone, TDD can generate several smaller red-green-refactor cycles.</p>

<p>Each layer operates at a different level of abstraction, receives different feedback, and has a different exit condition.</p>

<h2 id="the-outer-loop-the-execution-plan">The outer loop: the execution plan</h2>

<p>The outermost layer is the execution plan.</p>

<p>As I described in <a href="https://renanfranca.github.io/when-plan-mode-was-no-longer-enough.html">When Plan Mode Was No Longer Enough</a>, the execution plan gives the agent more than a list of tasks.</p>

<p>It describes:</p>

<ul>
  <li>why the change is needed;</li>
  <li>the current context;</li>
  <li>the desired final behavior;</li>
  <li>relevant constraints and decisions;</li>
  <li>the implementation milestones;</li>
  <li>the validation strategy;</li>
  <li>the final acceptance criteria.</li>
</ul>

<p>This loop begins with the current state of the repository and a desired destination.</p>

<p>The agent implements, validates, updates the plan with what it discovers, and continues until the complete plan satisfies its final acceptance criteria.</p>

<p>The important part is that the loop does not end merely because the agent says that it has finished.</p>

<p>It ends when the observable result matches what the plan defined as complete.</p>

<p>The execution plan therefore protects the destination.</p>

<p>Local implementation decisions can change. A milestone may reveal that an earlier assumption was incomplete. The agent may discover a better design while practising TDD.</p>

<p>The plan can evolve with those discoveries, but the final outcome must remain explicit.</p>

<h2 id="the-middle-loop-the-milestones">The middle loop: the milestones</h2>

<p>Inside the execution plan, there are milestones.</p>

<p>Each milestone has its own scope, validation commands, expected result, and acceptance criteria.</p>

<p>A milestone creates a smaller convergence point inside the larger implementation.</p>

<p>Instead of asking only:</p>

<blockquote>
  <p>Has the complete feature been implemented?</p>
</blockquote>

<p>The plan can repeatedly ask:</p>

<blockquote>
  <p>Has this meaningful part of the feature reached the state it promised?</p>
</blockquote>

<p>This distinction matters even though I no longer stop the agent after every milestone.</p>

<p>Earlier in my workflow, each milestone was also a human approval gate. I reviewed the implementation and explicitly authorized the next step.</p>

<p>Today, I usually allow the agent to implement the complete execution plan autonomously.</p>

<p>However, removing the human interruption did not remove the milestone loop.</p>

<p>The agent still needs to complete the milestone, run its validations, verify its acceptance criteria, record relevant decisions, and only then move forward.</p>

<p>The milestone remains a checkpoint even when I am not standing at the checkpoint.</p>

<p>It protects intermediate progress.</p>

<p>Without this layer, the agent could perform many technically valid operations without demonstrating that the implementation is moving through meaningful states toward the final result.</p>

<h2 id="the-inner-loop-tdd-and-executable-architecture">The inner loop: TDD and executable architecture</h2>

<p>Inside the milestones is the smallest and most active layer.</p>

<p>The TDD loop chooses the next observable behavior, writes a failing test, implements the minimum code necessary to make it pass, evaluates the opportunity for refactoring, and continues while the suite remains green.</p>

<p>One milestone can generate many of these cycles.</p>

<p>As I described in <a href="https://renanfranca.github.io/when-i-entrusted-tdd-to-an-ai-agent.html">When I Entrusted TDD to an AI Agent</a>, I eventually allowed Codex CLI to run these cycles autonomously through my <a href="https://github.com/renanfranca/codex-skills/blob/main/tdd%2Fbehavior-autonomous-quiet%2FSKILL.md">tdd-behavior-autonomous-quiet</a> skill.</p>

<p>But TDD alone was not enough.</p>

<p>An agent can write passing tests while moving behavior into the wrong architectural layer. It can also create tests that merely reproduce the structure of the production code.</p>

<p>For this reason, the loop also receives feedback from architectural tests such as <a href="https://github.com/seed4j/seed4j-cli/blob/main/src%2Ftest%2Fjava%2Fcom%2Fseed4j%2Fcli%2FHexagonalArchTest.java">HexagonalArchTest</a>.</p>

<p>These tests make architectural boundaries executable.</p>

<p>When the agent introduces an invalid dependency, the repository rejects the design.</p>

<p>The failure creates another correction cycle:</p>

<ol>
  <li>the behavioral test may already be green;</li>
  <li>an architectural rule fails;</li>
  <li>the agent changes the design;</li>
  <li>both behavioral and architectural tests run again;</li>
  <li>the implementation continues only when both forms of feedback agree.</li>
</ol>

<p>Vertical checkpoints add another feedback signal.</p>

<p>After a small number of TDD cycles, the agent must validate the feature through its public path. This prevents locally successful cycles from drifting into what I called the implementation details loop.</p>

<p>The inner layer therefore does more than ask whether the latest unit test passes.</p>

<p>It asks whether the behavior works, whether the design respects the architecture, and whether the accumulated implementation still produces progress through the feature’s public path.</p>

<h2 id="each-layer-asks-a-different-question">Each layer asks a different question</h2>

<p>Looking at the workflow as nested loops helped me understand why I need all three layers.</p>

<p>The execution plan asks:</p>

<blockquote>
  <p>Are we reaching the final outcome?</p>
</blockquote>

<p>The milestone asks:</p>

<blockquote>
  <p>Have we completed this meaningful stage of the implementation?</p>
</blockquote>

<p>The TDD and architecture loop asks:</p>

<blockquote>
  <p>Does the next behavior work without compromising the design?</p>
</blockquote>

<p>None of these questions replaces the others.</p>

<p>A green TDD cycle does not prove that a milestone is complete.</p>

<p>A completed milestone does not prove that the entire feature satisfies its acceptance criteria.</p>

<p>A completed execution plan does not prove that every internal design decision is good.</p>

<p>Each loop provides feedback at the scale where that feedback is useful.</p>

<h2 id="autonomy-depends-on-where-feedback-lives">Autonomy depends on where feedback lives</h2>

<p>Previously, much of this feedback lived in my interventions.</p>

<p>I inspected each step, questioned the direction, approved the next behavior, and decided when the agent could continue.</p>

<p>As I removed confirmation gates, I needed to move that judgment into executable constraints.</p>

<p>The execution plan made the destination explicit.</p>

<p>The milestone criteria made intermediate progress observable.</p>

<p>Behavior tests made functionality executable.</p>

<p>Architectural tests made design boundaries executable.</p>

<p>Vertical checkpoints made progress through the public path executable.</p>

<p>The agent did not become more autonomous because I stopped caring about the process.</p>

<p>It became more autonomous because the process could increasingly evaluate itself without waiting for me to repeat the same instructions.</p>

<h2 id="the-loops-still-end-with-me">The loops still end with me</h2>

<p>Even with these layers, I remain outside the complete implementation loop.</p>

<p>When the agent finishes, I review the result as a pull request.</p>

<p>I read the behavior tests, follow the production code that makes them pass, inspect the architectural decisions, refactor where necessary, and decide whether the change belongs in the codebase.</p>

<p>The loops reduce the number of routine decisions that depend on my immediate participation.</p>

<p>They do not transfer responsibility for the final code.</p>

<p>For now, the simplest names I have are:</p>

<ul>
  <li>the execution plan loop;</li>
  <li>the milestone loop;</li>
  <li>the TDD and architecture loop.</li>
</ul>

<p>Perhaps better names will emerge.</p>

<p>What matters to me is that I can finally see the structure that was already there.</p>

<p>I was not merely giving an agent a large prompt and waiting for code.</p>

<p>I was stacking feedback loops, each with its own scale, evidence, and exit condition.</p>

<p>I just did not know that this was what I was doing.</p>]]></content><author><name>Renan Franca</name></author><category term="tales-of-a-dev" /><summary type="html"><![CDATA[How execution plans, milestone acceptance criteria, and TDD with executable architecture became three nested feedback loops in my coding agent workflow.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://renanfranca.github.io/img/postbanners/2026-07-16-cover-i-had-already-built-three-agentic-loops.jpg" /><media:content medium="image" url="https://renanfranca.github.io/img/postbanners/2026-07-16-cover-i-had-already-built-three-agentic-loops.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">When I Entrusted TDD to an AI Agent</title><link href="https://renanfranca.github.io/when-i-entrusted-tdd-to-an-ai-agent.html" rel="alternate" type="text/html" title="When I Entrusted TDD to an AI Agent" /><published>2026-07-10T21:00:00+00:00</published><updated>2026-07-10T21:00:00+00:00</updated><id>https://renanfranca.github.io/when-i-entrusted-tdd-to-an-ai-agent</id><content type="html" xml:base="https://renanfranca.github.io/when-i-entrusted-tdd-to-an-ai-agent.html"><![CDATA[<p><img src="https://renanfranca.github.io/img/postbanners/2026-07-10-cover-when-i-entrusted-tdd-to-an-ai-agent.jpg" alt="cover image" /></p>

<h2 id="keeping-the-tests-under-my-control">Keeping the tests under my control</h2>

<p>When I first started using AI agents for software development, I kept a clear division of responsibilities.</p>

<p>I wrote the tests.</p>

<p>The agent implemented the production code and helped me refactor it.</p>

<p>At the time, I was using <a href="https://aider.chat/">Aider</a> through its CLI.</p>

<p>This arrangement allowed me to benefit from the agent without giving up control of the TDD process. I still chose the next behavior, wrote the failing test, watched it fail, and decided when the implementation was ready to be refactored.</p>

<p>More importantly, it kept my anxiety under control.</p>

<p>As I described in <a href="https://renanfranca.github.io/for-me-tdd-is-therapy.html">For Me, TDD Is Therapy</a>, TDD gives me a systematic way to move through the uncertainty of software development. Delegating production code while retaining the tests allowed me to preserve that process.</p>

<p>Then I watched a presentation that changed how I thought about this division.</p>

<h2 id="seeing-an-llm-practise-tdd">Seeing an LLM practise TDD</h2>

<p>The presentation was Lada Kesseler’s excellent <a href="https://youtu.be/_LSK2bVf0Lc?si=AW-QDxeCCgofLbDt">Augmented Coding: Mapping the Uncharted Territory</a>.</p>

<p>For the first time, I saw the possibility of allowing an LLM to write both the tests and the production code while still following the TDD flow.</p>

<p>Until then, I had assumed that keeping control of TDD meant keeping control of the tests.</p>

<p>Lada’s presentation showed me another possibility: perhaps I could delegate the entire red-green-refactor cycle while still making the process visible and inspectable.</p>

<p>I was so excited that I sent <a href="https://www.linkedin.com/in/lada-kesseler?utm_source=share_via&amp;utm_content=profile&amp;utm_medium=member_android">Lada Kesseler</a> a message on LinkedIn to thank her.</p>

<p>She very kindly sent me the prompt she had used to guide the LLM through TDD.</p>

<p>Reusable agent skills, at least in the form in which I use them today, did not exist yet. Even so, her presentation and prompt were already exploring the problems that skills would later help me address.</p>

<h2 id="my-first-tdd-skill">My first TDD skill</h2>

<p>When skills emerged, I used Lada’s prompt as the foundation for my first <a href="https://github.com/renanfranca/codex-skills/blob/main/tdd%2FSKILL.md">tdd skill</a>.</p>

<p>Sorry, Lada, if I somehow ruined your original prompt 😅.</p>

<p>I started using the skill with Codex CLI to implement new features inside existing business domains.</p>

<p>The process was extremely interactive.</p>

<p>The agent would:</p>

<ol>
  <li>write a comment describing the intention of the smallest test it wanted to implement;</li>
  <li>wait for my approval;</li>
  <li>implement the test and explain how it expected the test to fail;</li>
  <li>wait for approval again;</li>
  <li>implement the minimum production code necessary to make the test pass;</li>
  <li>wait before refactoring or moving to the next behavior.</li>
</ol>

<p>It was beautiful to watch.</p>

<p>The tests led the implementation. The expected failure was made explicit. Production code was added incrementally. Refactoring happened only while the test suite was green.</p>

<p>Most importantly, I could see the process.</p>

<p>I was no longer looking only at a final diff containing tests and production code. I could follow the sequence through which the design emerged.</p>

<p>However, I gradually started to notice another problem.</p>

<p>My need for control was forcing me to use the agent with the handbrake on.</p>

<h2 id="removing-confirmations-from-inside-the-cycle">Removing confirmations from inside the cycle</h2>

<p>My next experiment was <a href="https://github.com/renanfranca/codex-skills/blob/main/tdd-strict-cycle-confirmation%2FSKILL.md">tdd-strict-cycle-confirmation</a>.</p>

<p>Instead of requiring approval at several boundaries inside the same TDD cycle, the agent could complete red, green, and refactor before returning control to me.</p>

<p>The practical effect was simple.</p>

<p>I approved the next behavior. The agent wrote the failing test, implemented the minimum code, evaluated the opportunity for refactoring, reran the relevant tests, and then stopped before beginning another cycle.</p>

<p>This made the workflow considerably smoother.</p>

<p>I still had frequent opportunities to intervene, but I no longer needed to authorize every mechanical transition. The feedback loop remained small enough for me to understand what had happened without unnecessarily interrupting the agent.</p>

<p>For a while, this felt like the right balance.</p>

<p>Then I wanted to know what would happen if I removed even that confirmation gate.</p>

<h2 id="letting-the-agent-finish-the-feature">Letting the agent finish the feature</h2>

<p>I created another variation called <a href="https://github.com/renanfranca/codex-skills/blob/main/tdd-strict-autonomous%2FSKILL.md">tdd-strict-autonomous</a>.</p>

<p>This version no longer stopped after every completed cycle. It continued automatically through red, green, and refactor, pausing only when it encountered an exceptional situation such as ambiguous behavior, an unexpected failure, an architectural decision, or an environment problem.</p>

<p>At the time, I was trying to implement <a href="https://github.com/seed4j/seed4j-cli/issues/6">Registration of custom seed4j instances</a>.</p>

<p>The feature would allow the Seed4j CLI to register additional Seed4j module providers and discover their modules at runtime.</p>

<p>Even I did not know exactly what the technical solution should look like.</p>

<p>That uncertainty was part of the experiment. Instead of directing every design decision, I wanted to observe what the agent would discover through TDD.</p>

<p>Unfortunately, the experiment exposed a serious problem.</p>

<h2 id="the-implementation-details-loop">The implementation details loop</h2>

<p>I called the problem the <strong>implementation details loop</strong>.</p>

<p>The agent continued taking small steps. Each individual step appeared reasonable. Tests were being added, production code was changing, and the suite kept moving forward.</p>

<p>But the implementation was no longer moving meaningfully toward the feature.</p>

<p>The agent had become absorbed in the internal structure it was creating.</p>

<p>A new class encouraged a new test class. That test exposed another internal detail. Supporting that detail required another production abstraction, which then received its own tests.</p>

<p>The cycles were small, but the feature was disappearing from view.</p>

<p>When I inspected the Codex CLI session, I found so much information that I could not identify the exact moment when the implementation had lost its direction.</p>

<p>The problem was not a lack of activity.</p>

<p>The problem was that local progress no longer implied progress through the feature’s public path.</p>

<p>I abandoned the implementation and returned to <a href="https://github.com/renanfranca/codex-skills/blob/main/tdd-strict-cycle-confirmation%2FSKILL.md">tdd-strict-cycle-confirmation</a>.</p>

<p>This time, I wanted to find the precise cycle in which the agent started following implementation details instead of behavior.</p>

<p>After finding it, I told Codex CLI that it was trapped in a loop and added this instruction to the TDD skills:</p>

<blockquote>
  <p>Run a vertical checkpoint at least every two cycles using the public path of the feature.</p>
</blockquote>

<p>The agent could still work through small units, but it now had to regularly prove that those units composed into observable progress.</p>

<p>This improved the situation, but it did not solve everything.</p>

<h2 id="making-the-autonomous-process-quieter">Making the autonomous process quieter</h2>

<p>The agent still produced a large volume of messages.</p>

<p>Detailed output had initially helped me trust the process. Once the agent became autonomous, however, the same volume made it harder to notice the information that actually mattered.</p>

<p>Routine file reads, expected failures, test commands, green transitions, and minor refactorings created a long stream of activity.</p>

<p>I created <a href="https://github.com/renanfranca/codex-skills/blob/main/tdd-strict-autonomous-quiet%2FSKILL.md">tdd-strict-autonomous-quiet</a> to reduce that noise.</p>

<p>Quiet does not mean merely writing shorter messages.</p>

<p>It means emitting fewer messages.</p>

<p>The agent keeps ordinary cycle details internal and interrupts me only for meaningful events:</p>

<ul>
  <li>an unexpected failure;</li>
  <li>a blocked environment;</li>
  <li>a public-path checkpoint failure;</li>
  <li>an architectural or public API decision;</li>
  <li>a significant refactoring;</li>
  <li>a final summary.</li>
</ul>

<p>This made autonomous execution much easier to follow.</p>

<p>However, the quieter output also made another problem clearer.</p>

<p>The agent was still creating too many tests tied to the structure of the production code.</p>

<h2 id="tests-should-not-mirror-production-topology">Tests should not mirror production topology</h2>

<p>I frequently saw one test class for every production class.</p>

<p>When the implementation extracted a helper, resolver, parser, mapper, or adapter, the agent often created a corresponding test.</p>

<p>The final suite could have excellent coverage while still being fragile.</p>

<p>A refactoring that renamed, moved, split, or merged production classes could require several tests to change even when no observable behavior had changed.</p>

<p>I could correct the direction manually, but doing so repeatedly was becoming too much work.</p>

<p>The agent was failing to apply a concept presented in complementary ways in these two articles:</p>

<ol>
  <li><a href="https://blog.cleancoder.com/uncle-bob/2017/10/03/TestContravariance.html">Test Contra-variance, by Uncle Bob</a>;</li>
  <li><a href="https://tidyfirst.substack.com/p/additional-testing-after-refactoring">Additional Testing After Refactoring, by Kent Beck</a>.</li>
</ol>

<p>My interpretation is that the shape of the tests should not follow the shape of the production code.</p>

<p>Production code may become more detailed as the design evolves. It may gain more classes, functions, modules, and internal abstractions.</p>

<p>The tests do not need to reproduce that topology.</p>

<p>They should remain attached to observable behavior and stable contracts.</p>

<p>A test is suspicious when it fails merely because the production code was internally reorganized while preserving the same behavior.</p>

<h2 id="architecture-defines-stable-observation-points">Architecture defines stable observation points</h2>

<p>Before improving the TDD skill again, I realized that the agent was also failing to respect the chosen hexagonal architecture consistently.</p>

<p>This matters because architecture helps identify useful and stable observation points for tests.</p>

<p>A command-line feature can often be tested through the CLI boundary. An application behavior can be exercised through an application service. Domain rules can be verified through domain contracts.</p>

<p>Internal adapters and implementation helpers usually do not need tests merely because they exist.</p>

<p>For a practical explanation of this relationship, I recommend <a href="https://www.youtube.com/live/PE57mE3qaHI?is=seGIWqGBGgq8cKdA">TDD in Hexagonal and Clean Architecture</a>, by <a href="https://www.linkedin.com/in/valentinajemuovic">Valentina Jemuović</a>.</p>

<p>Without enforceable architectural boundaries, an agent can gradually move behavior into the wrong layer while continuing to produce passing tests.</p>

<p>The tests may verify the code it created without protecting the design I intended.</p>

<p>Prompt instructions alone were not enough.</p>

<p>I needed the repository itself to reject architectural violations.</p>

<h2 id="making-the-architecture-executable">Making the architecture executable</h2>

<p>I implemented architectural tests such as <a href="https://github.com/seed4j/seed4j-cli/blob/main/src%2Ftest%2Fjava%2Fcom%2Fseed4j%2Fcli%2FHexagonalArchTest.java">HexagonalArchTest</a>.</p>

<p>These tests use ArchUnit to enforce rules including:</p>

<ul>
  <li>domain code must not depend on infrastructure;</li>
  <li>application code must not depend on infrastructure adapters;</li>
  <li>primary adapters must not depend directly on secondary adapters;</li>
  <li>secondary adapters must not depend on the application layer;</li>
  <li>bounded contexts must communicate through the intended boundaries;</li>
  <li>domain ports must represent business capabilities;</li>
  <li>composition code must remain in the composition root.</li>
</ul>

<p>This changed my relationship with the agent.</p>

<p>I no longer needed to rely only on a written instruction saying, “Respect the hexagonal architecture.”</p>

<p>The test suite could detect violations.</p>

<p>The architecture became executable feedback inside the same loop the agent was already following.</p>

<p>When an architectural test failed, the agent received concrete evidence that its current design had crossed a boundary.</p>

<h2 id="from-strict-tdd-to-behavior-focused-tdd">From strict TDD to behavior focused TDD</h2>

<p>The remaining task was to combine everything I had learned into another skill.</p>

<p>I created <a href="https://github.com/renanfranca/codex-skills/blob/main/tdd-behavior-autonomous-quiet%2FSKILL.md">tdd-behavior-autonomous-quiet</a>.</p>

<p>It preserves autonomous red-green-refactor cycles and quiet output, but it adds an important requirement: tests must follow observable behavior, public contracts, user journeys, or intentionally stable component APIs.</p>

<p>They must not follow production file and class structure.</p>

<p>Before creating a new test class, the agent must effectively answer three questions:</p>

<ol>
  <li>Which behavior is being specified?</li>
  <li>Through which public or stable API is that behavior observed?</li>
  <li>Why is no existing behavior test suite the appropriate home for it?</li>
</ol>

<p>Extracting a new internal class does not automatically justify creating a new test class.</p>

<p>Moving production code does not automatically justify moving tests.</p>

<p>A lower-level test is appropriate only when the component has a stable API that is independently meaningful to a caller.</p>

<p>The agent should prefer the highest useful observation point that still provides clear and sufficiently fast feedback.</p>

<p>This was the missing piece.</p>

<h2 id="combining-the-skill-with-execution-plans">Combining the skill with execution plans</h2>

<p>Today, I use <code>tdd-behavior-autonomous-quiet</code> to implement execution plans created through the process I described in <a href="https://renanfranca.github.io/when-plan-mode-was-no-longer-enough.html">When Plan Mode Was No Longer Enough</a>.</p>

<p>Previously, I asked the agent to implement one milestone at a time. I reviewed the result and explicitly authorized the next milestone.</p>

<p>I no longer do that.</p>

<p>I realized that a milestone does not always correspond to a complete feature or even a complete design decision.</p>

<p>Sometimes I reviewed an intermediate state and corrected something that would naturally have been resolved in a later milestone. My intervention was based on incomplete information.</p>

<p>Now I wait for the entire execution plan to be implemented.</p>

<p>The execution plan gives the agent the destination, context, constraints, validation strategy, and important decisions.</p>

<p>The TDD skill controls how the implementation moves toward that destination.</p>

<p>The architectural tests protect the boundaries of the system.</p>

<p>The vertical checkpoints verify that local cycles continue producing progress through the public path.</p>

<p>Together, these elements allow the agent to work autonomously without reducing the process to “generate everything and add tests afterwards.”</p>

<h2 id="reviewing-the-result-as-a-pull-request">Reviewing the result as a pull request</h2>

<p>The result is usually well designed code with tests that genuinely verify behavior.</p>

<p>I still find opportunities for refactoring and improvement.</p>

<p>But the experience now feels like reviewing a very well written pull request.</p>

<p>I begin with the first behavior test.</p>

<p>I understand what it protects.</p>

<p>Then I examine the production code that makes it pass.</p>

<p>I continue following that relationship between behavior and implementation until I complete the review.</p>

<p>A practical example is the pull request <a href="https://github.com/seed4j/seed4j-cli/pull/272/commits">enhance apply plan dependency status</a>.</p>

<p>The first commit contains exactly what the agent developed, without any intervention from me.</p>

<p>The remaining commits show the adjustments I made during my review.</p>

<p>That distinction is important because it makes the result inspectable.</p>

<p>It shows what autonomous implementation produced and where my judgment still changed the code.</p>

<h2 id="autonomy-introduced-a-different-waiting-problem">Autonomy introduced a different waiting problem</h2>

<p>Waiting between three and six minutes for the agent to deliver the implementation still bothers me.</p>

<p>The agent writes quickly enough that I cannot meaningfully follow every operation in real time.</p>

<p>At the same time, it is slow enough to leave me waiting and disconnected from the problem solving process.</p>

<p>Ideally, the interaction would <a href="https://newsletter.kentbeck.com/p/the-precious-eyeblink">respond within the precious 400 milliseconds</a>, preserving the feeling of a continuous workflow.</p>

<p>Instead, I delegate the work, wait, and later receive an implementation that I need to load into my mind.</p>

<p>This creates a different kind of cognitive cost.</p>

<h2 id="i-am-not-a-multitasker">I am not a multitasker</h2>

<p>I am not a multitasker.</p>

<p>I can perform tasks sequentially, and TDD supported this extremely well.</p>

<p>After completing a red-green-refactor cycle, I had a natural stopping point. If I was interrupted, I knew that the suite was green and the current behavior had been completed.</p>

<p>When I returned, the next failing test or pending behavior told me where to continue.</p>

<p>Reviewing an autonomous implementation is different.</p>

<p>If I am interrupted in the middle of the review, I need to mark which test I have already examined and which one I should read next.</p>

<p>I also carry a greater cognitive load because I did not participate directly in each problem solving step.</p>

<p>The final code may be clear, but the path that produced it is not fixed in my mind in the same way as code I developed myself.</p>

<p>The agent has reduced the effort required to produce the implementation.</p>

<p>It has not eliminated the effort required for me to understand and assume responsibility for it.</p>

<h2 id="answering-my-previous-questions">Answering my previous questions</h2>

<p>In <a href="https://renanfranca.github.io/for-me-tdd-is-therapy.html#ai-agents-brought-the-anxiety-back">For Me, TDD Is Therapy</a>, I asked three questions.</p>

<p>I can now answer two of them.</p>

<blockquote>
  <p>Am I limiting the AI agent by requiring it to work through TDD?</p>
</blockquote>

<p>I reduced my need for control as much as I currently consider responsible.</p>

<p>I no longer write the tests myself. I do not approve every test, every green implementation, every refactoring, every cycle, or every milestone.</p>

<p>I entrust the TDD process to the agent until the complete execution plan has been implemented or a meaningful exception requires my attention.</p>

<p>The constraints remain strict, but routine control no longer depends on me.</p>

<blockquote>
  <p>How can I reproduce the TDD feedback loop when working with an AI agent?</p>
</blockquote>

<p>I moved toward it gradually.</p>

<p>Initially, every transition was visible and required confirmation. Later, I approved only complete cycles. Then I allowed cycles to continue autonomously.</p>

<p>Today, most routine steps remain internal, but the agent surfaces relevant decisions, failures, checkpoints, and refactorings.</p>

<p>I no longer experience the feedback loop by personally performing each step.</p>

<p>Instead, I make the loop executable through the skill, the test suite, the architectural rules, and the public path checkpoints.</p>

<p>That is not the same experience as practising TDD manually, but it preserves the properties I care about.</p>

<p>The third question remains more difficult.</p>

<blockquote>
  <p>Does the agent genuinely practise TDD, or does it develop the solution first and create the tests afterwards?</p>
</blockquote>

<p>My friend <a href="https://www.linkedin.com/in/victor-perone-696634a7?utm_source=share_via&amp;utm_content=profile&amp;utm_medium=member_android">Victor Perone</a> introduced me to a few machine learning concepts.</p>

<p>That alone was enough for me to realize how different this field is from my own.</p>

<p>To answer this question properly, I would need to investigate much more deeply what happens inside an LLM while it appears to perform a TDD cycle.</p>

<p>Anthropic itself is still investigating how language models internally reach their outputs, as shown in <a href="https://transformer-circuits.pub/2025/attribution-graphs/biology.html">On the Biology of a Large Language Model</a> and <a href="https://transformer-circuits.pub/2026/workspace/index.html">Verbalizable Representations Form a Global Workspace in Language Models</a>.</p>

<p>For now, I can verify the external process.</p>

<p>I can require a failing behavior test before production code changes.</p>

<p>I can inspect the failure.</p>

<p>I can constrain the green implementation.</p>

<p>I can require refactoring only while the suite is green.</p>

<p>I can enforce architectural boundaries and repeatedly validate the feature through its public path.</p>

<p>I still cannot claim to know what happened internally before the agent displayed each step.</p>

<h2 id="what-i-actually-learned-to-trust">What I actually learned to trust</h2>

<p>I did not learn to trust every line generated by an AI agent.</p>

<p>I learned to trust a process with executable constraints.</p>

<p>The agent owns the individual TDD cycles.</p>

<p>The execution plan preserves the destination.</p>

<p>Behavior tests protect what users and callers can observe.</p>

<p>Architectural tests protect the system’s boundaries.</p>

<p>Vertical checkpoints prevent small implementation steps from losing the feature.</p>

<p>I remain responsible for reviewing the result and deciding whether it belongs in the codebase.</p>

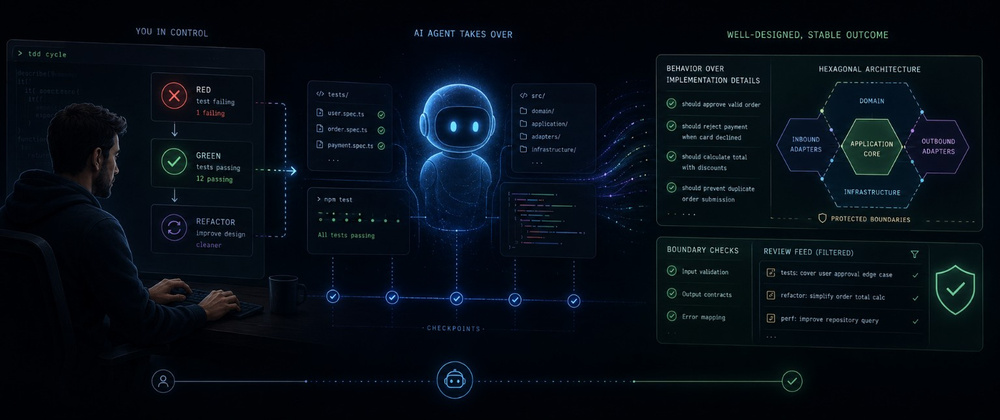
<p>Delegating TDD did not remove me from software development.</p>

<p>It changed where I participate.</p>]]></content><author><name>Renan Franca</name></author><category term="tales-of-a-dev" /><summary type="html"><![CDATA[How I gradually removed confirmation gates, added behavioral and architectural guardrails, and learned to let Codex CLI practise TDD autonomously.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://renanfranca.github.io/img/postbanners/2026-07-10-cover-when-i-entrusted-tdd-to-an-ai-agent.jpg" /><media:content medium="image" url="https://renanfranca.github.io/img/postbanners/2026-07-10-cover-when-i-entrusted-tdd-to-an-ai-agent.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">For Me, TDD Is Therapy</title><link href="https://renanfranca.github.io/for-me-tdd-is-therapy.html" rel="alternate" type="text/html" title="For Me, TDD Is Therapy" /><published>2026-07-07T18:00:00+00:00</published><updated>2026-07-07T18:00:00+00:00</updated><id>https://renanfranca.github.io/for-me-tdd-is-therapy</id><content type="html" xml:base="https://renanfranca.github.io/for-me-tdd-is-therapy.html"><![CDATA[<p><img src="https://renanfranca.github.io/img/postbanners/2026-07-07-cover-for-me-tdd-is-therapy.jpg" alt="cover image" /></p>

<h2 id="the-anxiety-i-recognized">The anxiety I recognized</h2>

<p>While watching the podcast <a href="https://youtu.be/ddHQQtjIOpw?t=4785&amp;is=ZgGjff_muSzUlo6c">How Kent Beck Shapes the Software Engineering Industry</a>, I heard Kent Beck describe the anxiety he felt while developing software and how Test-Driven Development helped him deal with it.</p>

<p>I immediately recognized that feeling.</p>

<p>I have felt it since my first contact with programming in 2006, during my Computer Science degree.</p>

<p>I never knew exactly where to begin an implementation.</p>

<p>The process was always different. It was highly intuitive and depended heavily on my mood, motivation, and confidence on that particular day.</p>

<p>Sometimes I would spend too much time thinking about the best place to start. Other times I would begin somewhere almost randomly and hope that the implementation would eventually reveal its shape.</p>

<p>There was no process I could trust.</p>

<h2 id="when-working-code-was-not-enough">When working code was not enough</h2>

<p>The uncertainty was so intense that, when something I implemented worked on the first try, I did not trust it.</p>

<p>A successful result was not enough to convince me.</p>

<p>I needed to deliberately break the production code and repeat the manual test. Only after watching the behavior fail could I feel confident that my manual verification was actually exercising the change.</p>

<p>Otherwise, I was left with uncomfortable questions:</p>

<ul>
  <li>Did the implementation really work?</li>
  <li>Was my manual test actually exercising the changed behavior?</li>
  <li>Did it work for the reason I expected?</li>
  <li>Was there some accidental condition making everything appear correct?</li>
</ul>

<p>I did not have a reliable way to move from uncertainty to confidence.</p>

<h2 id="for-me-tdd-is-therapy">For me, TDD is therapy</h2>

<p>For me, TDD is therapy.</p>

<p>That is what I believe.</p>

<p>Not because TDD removes uncertainty from software development. It does not.</p>

<p>It gives me a systematic process for moving through that uncertainty.</p>

<p>I do not need to discover the entire implementation before I begin. I only need to identify the next observable behavior and express it as a test.</p>

<p>Then I watch it fail.</p>

<p>I implement enough to make it pass.</p>

<p>I refactor while keeping the behavior protected.</p>

<p>And then I repeat the cycle.</p>

<p>This process gives me somewhere to begin and tells me what to do next.</p>

<p>On my best days, it gives structure to my ideas.</p>

<p>On my worst days, it allows me to remain productive even when motivation and confidence are low.</p>

<p>That is my main reason for practising TDD.</p>

<p>The other benefits matter: executable documentation, regression protection, simpler designs, shorter feedback loops, and the confidence to refactor.</p>

<p>But my primary motivation is more personal.</p>

<p>TDD gives me a process I can follow when my intuition is not enough.</p>

<h2 id="how-i-started-practising-tdd">How I started practising TDD</h2>

<p>I started deliberately practising TDD in December 2022 while contributing to the open source project now known as <a href="https://seed4j.com/">Seed4j</a>.</p>

<p>In <a href="https://renanfranca.github.io/how-did-i-earn-money-to-fix-an-issue-from-an-open-source-software.html">How did I earn money to fix an issue from an Open Source Software?</a>, I described some of that first experience.</p>

<p>At the time, Seed4j was still called JHipster Lite.</p>

<p>That contribution also taught me an important distinction. I initially believed I was doing TDD, but I was actually writing tests before the implementation without necessarily allowing the tests to guide the design.</p>

<p>I was doing <em>test first</em>.</p>

<p>Learning that distinction did not discourage me. It gave me a clearer direction.</p>

<p>Since then, TDD has become much more than writing tests before production code. It has become the process through which I investigate a problem, discover behavior, make design decisions, and build confidence incrementally.</p>

<p>Two books were especially important in shaping how I understand this process:</p>

<ul>
  <li><em>Test-Driven Development: By Example</em>, by Kent Beck;</li>
  <li><em>TDD</em>, by Jason Gorman.</li>
</ul>

<h2 id="the-explanation-i-grew-tired-of-repeating">The explanation I grew tired of repeating</h2>

<p>Before adopting this process, I grew tired of repeatedly explaining the same thing to people who assigned me a task:</p>

<blockquote>
  <p>This change is simple. What takes time is manually testing the entire system to ensure that nothing has been broken.</p>
</blockquote>

<p>The code change might require only a few lines.</p>

<p>The real cost came afterwards.</p>

<p>I needed to navigate through the application, recreate scenarios, remember which related features might be affected, and manually verify that an apparently unrelated behavior had not changed.</p>

<p>Then I needed to repeat much of that work after every adjustment.</p>

<p>Without automated tests, even a simple change carried a large and mostly invisible validation cost.</p>

<p>TDD did not merely help me write the change. It helped me build the mechanism through which I could safely change it again.</p>

<h2 id="when-the-team-does-not-want-tdd">When the team does not want TDD</h2>

<p>I respect teams that do not want to work with TDD.</p>

<p>I think it is unfortunate, but I accept it.</p>

<p>I introduce the idea once. I explain why I believe it would help. If the team decides not to adopt it, I do not turn the subject into a permanent argument.</p>

<p>Life goes on.</p>

<p>However, for my own implementations, I still prefer to work through tests.</p>

<p>When necessary, I create a private fork and maintain a branch containing the tests. I write the tests and implement the change there. Then I open the pull request containing only the production code expected by the project.</p>

<p>This is not my preferred outcome. I would rather have the tests maintained alongside the implementation so that the entire team could benefit from them.</p>

<p>But even when a project has insufficient test coverage, abandoning my process makes the work more difficult for me.</p>

<p>The private branch allows me to preserve the feedback loop I need to implement the change with confidence.</p>

<h2 id="ai-agents-brought-the-anxiety-back">AI agents brought the anxiety back</h2>

<p>AI agents changed my development workflow significantly.</p>

<p>They can explore a codebase, propose a plan, implement changes, execute tests, refactor code, and document decisions much faster than I could do all of those things alone.</p>

<p>But they also introduced new forms of anxiety.</p>

<p>I started asking myself:</p>

<blockquote>
  <p>Am I limiting the AI agent by requiring it to work through TDD?</p>
</blockquote>

<blockquote>
  <p>How can I reproduce the TDD feedback loop when working with an AI agent?</p>
</blockquote>

<blockquote>
  <p>Does the agent genuinely practise TDD, or does it develop the solution first and create the tests afterwards?</p>
</blockquote>

<p>That final question bothers me the most.</p>

<p>An agent can produce a test and production code in the same implementation. The final diff may look exactly like the result of TDD.</p>

<p>But the final diff does not reveal the process.</p>

<p>Did the test fail before the implementation existed?</p>

<p>Did that failure provide useful information?</p>

<p>Did the test guide a design decision?</p>

<p>Was only enough code written to satisfy the next behavior?</p>

<p>Or did the agent first construct the complete solution and then create tests that confirmed what it had already built?</p>

<p>The resulting repository may contain the same files, but the development process is not the same.</p>

<h2 id="the-process-still-matters">The process still matters</h2>

<p>In <a href="https://renanfranca.github.io/when-plan-mode-was-no-longer-enough.html">When Plan Mode Was No Longer Enough</a>, I described how execution plans and smaller milestones helped me reduce the volume of code I needed to review after working with an agent.</p>

<p>That approach gave me more control over the size of each change.</p>

<p>But it did not reproduce the TDD experience.</p>

<p>A milestone can still contain production code, tests, and refactoring created together. It can be small enough to review while still hiding the sequence through which the design emerged.</p>

<p>This matters to me because TDD is not valuable only because of the tests left behind.</p>

<p>The sequence matters.</p>

<p>The feedback matters.</p>

<p>The small decisions made after each failure matter.</p>

<p>Most importantly, the process changes how I think while implementing the solution.</p>

<p>For years, TDD gave me a way to manage the anxiety of not knowing where to begin.</p>

<p>Now AI agents are forcing me to examine that process more carefully than ever.</p>

<p>I need to understand which parts of TDD must remain visible, which parts can be delegated, and how I can know whether an agent is following the process rather than merely reproducing its final appearance.</p>

<p>I will explore those questions in my next post.</p>]]></content><author><name>Renan Franca</name></author><category term="tales-of-a-dev" /><summary type="html"><![CDATA[How TDD gave me a systematic way to work through the anxiety and uncertainty of software development—and how AI agents brought some of that anxiety back.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://renanfranca.github.io/img/postbanners/2026-07-07-cover-for-me-tdd-is-therapy.jpg" /><media:content medium="image" url="https://renanfranca.github.io/img/postbanners/2026-07-07-cover-for-me-tdd-is-therapy.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">When Plan Mode Was No Longer Enough</title><link href="https://renanfranca.github.io/when-plan-mode-was-no-longer-enough.html" rel="alternate" type="text/html" title="When Plan Mode Was No Longer Enough" /><published>2026-07-05T15:00:00+00:00</published><updated>2026-07-05T15:00:00+00:00</updated><id>https://renanfranca.github.io/when-plan-mode-was-no-longer-enough</id><content type="html" xml:base="https://renanfranca.github.io/when-plan-mode-was-no-longer-enough.html"><![CDATA[<p><img src="https://renanfranca.github.io/img/postbanners/2026-07-05-cover-from-plan-mode-to-execution-plans.jpg" alt="cover image" /></p>

<h2 id="plan-mode-initially-felt-like-enough">Plan Mode initially felt like enough</h2>

<p>My workflow with Codex CLI used to be relatively simple.</p>

<p>I would enter Plan Mode, discuss what I wanted to implement, refine the scope, question some decisions, and eventually reach a plan that looked reasonable.</p>

<p>Then I would leave Plan Mode and ask Codex to execute it.</p>

<p>For a while, this felt like a good separation of responsibilities. First, we would think. Then, the agent would implement.</p>

<p>But eventually, it stopped being enough.</p>

<h2 id="my-first-disappointment-with-ai-agents">My first disappointment with AI agents</h2>

<p>The problem was not that Codex could not generate the code.</p>

<p>The problem was that it could generate too much code at once.</p>

<p>After a large implementation, I would receive a substantial set of changes that I still needed to understand, review, refactor, and validate. Sometimes the implementation was technically correct, but it contained decisions I would not have made myself.</p>

<p>Other times, the tests passed, but some of them were tied to implementation details instead of protecting actual behavior.</p>

<p>I started to feel exhausted after these sessions.</p>

<p>The agent had accelerated implementation, but it had also created a large review queue for me. I was no longer spending most of my energy writing code. I was spending it trying to absorb, validate, and reshape everything the agent had produced.</p>

<p>The bottleneck had moved.</p>

<p>Codex was not struggling to generate code. I was struggling to review that code responsibly.</p>

<p>This was my first real disappointment with AI agents.</p>

<p>Not because they were incapable, but because I realized that generating code faster does not automatically make the entire development process faster.</p>

<h2 id="shrinking-the-feedback-loop">Shrinking the feedback loop</h2>

<p>While searching for a better approach, I found the OpenAI Cookbook article <a href="https://developers.openai.com/cookbook/articles/codex_exec_plans">Using PLANS.md for multi-hour problem solving</a>.</p>

<p>It describes an execution plan, or ExecPlan, as a self-contained and continuously updated document that an agent can follow while implementing a complex change.</p>

<p>An ExecPlan is more than a list of tasks.</p>

<p>It includes the purpose of the change, the current context, the desired behavior, implementation milestones, validation commands, risks, decisions, progress, and lessons learned.</p>

<p>The concept that made the biggest difference for me was dividing the implementation into milestones.</p>

<p>Instead of asking Codex to execute the entire plan, I started asking it to implement one milestone at a time.</p>

<p>After each milestone, I could:</p>

<ul>
  <li>review a smaller volume of code;</li>
  <li>refactor while the context was still manageable;</li>
  <li>verify whether the tests protected behavior;</li>
  <li>question design decisions;</li>
  <li>run focused validation;</li>
  <li>update the plan with what we had learned;</li>
  <li>decide whether the implementation was ready to continue.</li>
</ul>

<p>Only after I considered the result good enough would I ask Codex to implement the next milestone.</p>

<p>The milestone became the unit of collaboration between me and the agent.</p>

<h2 id="turning-the-idea-into-a-skill">Turning the idea into a skill</h2>

<p>The OpenAI Cookbook article is dated October 7, 2025, and its current version recommends <code>gpt-5.2-codex</code>.</p>

<p>After GPT-5.5 was released, I asked the model to revise the original instructions and make them more appropriate for the newer model.</p>

<p>The result required fewer step-by-step directions and placed more emphasis on the properties the final execution plan should preserve.</p>

<p>I then transformed those instructions into my <a href="https://github.com/renanfranca/codex-skills/blob/main/implement-execplan/SKILL.md">implement-execplan</a> skill.</p>

<p>The skill defines an ExecPlan as a living document. It requires the agent to maintain sections such as:</p>

<ul>
  <li>purpose and scope;</li>
  <li>existing context;</li>
  <li>desired end state;</li>
  <li>implementation milestones;</li>
  <li>progress;</li>
  <li>decisions and their rationale;</li>
  <li>risks and mitigations;</li>
  <li>validation strategy;</li>
  <li>lessons learned.</li>
</ul>

<p>It also requires each milestone to contain concrete changes, validation commands, and observable acceptance criteria.</p>

<p>However, the most important part of my workflow does not come only from the structure of the document.</p>

<p>It comes from controlling when the next milestone starts.</p>

<p>I do not want the agent to finish faster than I can understand the change.</p>

<h2 id="a-real-example-in-seed4j-cli">A real example in seed4j-cli</h2>

<p>A concrete example came from a feature I implemented in <a href="https://github.com/seed4j/seed4j-cli"><code>seed4j-cli</code></a>.</p>

<p>The ChatGPT Android app allows me to use a GitHub integration that can read repositories. I used it to inspect the project and discuss the feature with GPT-5.5 in an experience similar to Codex CLI Plan Mode.</p>

<p>After refining the scope, I created the issue <a href="https://github.com/seed4j/seed4j-cli/issues/270">Enhance <code>apply --plan</code> with dependency chain status</a>.</p>

<p>The goal was to improve the output of:</p>

<pre><code class="language-bash">seed4j apply &lt;module&gt; --project-path . --plan
</code></pre>

<p>The command already displayed resolved parameters, but it did not explain whether the module dependencies had already been applied, were still pending, or required an explicit feature choice.</p>

<p>When it was time to implement the feature, I asked Codex CLI to read the issue and use my skill to create this execution plan:</p>

<p><a href="https://github.com/renanfranca/seed4j-cli-ai-context/blob/main/shared%2Fdone%2F2026-06-26_FEATURE_apply-plan-dependency-status-exec-plan.md">2026-06-26_FEATURE_apply-plan-dependency-status-exec-plan.md</a></p>

<p>The work was divided into four milestones:</p>

<ol>
  <li>establish the living execution plan;</li>
  <li>add the status of direct module dependencies;</li>
  <li>add feature dependency satisfaction and pending choices;</li>
  <li>update documentation and validate formatting.</li>
</ol>

<p>This division gave me natural stopping points.</p>

<p>After the direct module dependency behavior was implemented, I could review it before introducing the more complex feature dependency rules.</p>

<p>After the behavior was stable, documentation and formatting could be handled separately.</p>

<p>What changed was not necessarily the quality of every generated line.</p>

<p>What changed was the size of the feedback loop.</p>

<h2 id="the-document-became-part-of-the-work">The document became part of the work</h2>

<p>There was another benefit I had not fully anticipated.</p>

<p>The execution plan became a record of the implementation.</p>

<p>During the work, Codex continuously updated the document with completed milestones, design decisions, validation results, discovered risks, unrelated repository problems, and lessons learned.</p>

<p>For example, the final document records why dependency planning remained in the CLI primary adapter, why CLI integration tests were used as the behavior contract, and why the dependency traversal needed to be deterministic and cycle-safe.</p>

<p>It also records that the repository-wide formatting check contained pre-existing failures unrelated to the feature, while the files changed by the implementation passed focused formatting validation.</p>

<p>Without the execution plan, much of that context would have disappeared inside the conversation.</p>

<p>The code would remain, but the reasoning behind several decisions would be lost.</p>

<p>Instead, I ended the implementation with both working code and a document describing how the implementation evolved.</p>

<p>In another post, I plan to explain what I started doing with these files instead of simply discarding them after the feature was completed.</p>

<h2 id="what-this-approach-still-does-not-solve">What this approach still does not solve</h2>

<p>Execution plans helped me control the size of generated changes, but they did not solve everything.</p>

<p>Codex can still create tests that are too closely tied to implementation details. A smaller milestone makes those tests easier to identify, but it does not automatically make them good.</p>

<p>This approach also does not reproduce the TDD experience I was used to.</p>

<p>In traditional TDD, the feedback loop begins with a failing test that expresses the next behavior. The design emerges through small cycles of failure, implementation, and refactoring.</p>

<p>An ExecPlan organizes implementation into milestones, but a milestone can still contain too much production code before the right behavioral tests are established.</p>

<p>I have made progress in this area by combining execution plans with other skills and more explicit testing workflows.</p>

<p>That deserves its own post because it changes not only how the agent implements a feature, but also how I participate during the implementation.</p>

<h2 id="regaining-control-without-rejecting-the-agent">Regaining control without rejecting the agent</h2>

<p>My first reaction to the review burden could have been to reduce my use of AI agents.</p>

<p>Instead, I changed the granularity of the work I delegated to them.</p>

<p>The answer was not a more detailed initial conversation followed by an even larger autonomous implementation.</p>

<p>The answer was a living plan, smaller milestones, explicit validation, and deliberate stopping points.</p>

<p>I still review the code.</p>

<p>I still refactor it.</p>

<p>I still question tests and design decisions.</p>

<p>The execution plan does not remove my responsibility from the process. It gives me a structure that makes that responsibility sustainable.</p>

<p>For me, that has become one of the most important lessons about working with coding agents:</p>

<p>The agent’s ability to generate code is not the only limit that matters.</p>

<p>My ability to understand, validate, and improve that code matters just as much.</p>]]></content><author><name>Renan Franca</name></author><category term="tales-of-a-dev" /><summary type="html"><![CDATA[How milestone-based execution plans helped me reduce the review burden, preserve decisions, and regain control over code generated by Codex CLI.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://renanfranca.github.io/img/postbanners/2026-07-05-cover-from-plan-mode-to-execution-plans.jpg" /><media:content medium="image" url="https://renanfranca.github.io/img/postbanners/2026-07-05-cover-from-plan-mode-to-execution-plans.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Intention in Portuguese, Code in English</title><link href="https://renanfranca.github.io/intention-in-portuguese-code-in-english.html" rel="alternate" type="text/html" title="Intention in Portuguese, Code in English" /><published>2026-07-02T22:00:00+00:00</published><updated>2026-07-02T22:00:00+00:00</updated><id>https://renanfranca.github.io/intention-in-portuguese-code-in-english</id><content type="html" xml:base="https://renanfranca.github.io/intention-in-portuguese-code-in-english.html"><![CDATA[<p><img src="https://renanfranca.github.io/img/postbanners/2026-07-02-cover-intention-in-portuguese-code-in-english.jpg" alt="cover image" /></p>

<h2 id="from-english-prompts-to-portuguese-intention">From English prompts to Portuguese intention</h2>

<p>I am Brazilian, and my native language is Portuguese.</p>

<p>Since the launch of ChatGPT, I got used to interacting with it in English. At the time, it was not just a preference. I clearly felt that the responses were better, and it also made my work easier when I wanted to generate code, documentation, method names, tests, and examples for my open-source projects.</p>

<p>Because most of the projects I contribute to use English as the standard language, using English with the AI felt natural.</p>

<p>But something changed.</p>

<p>Today, when I use Codex CLI for programming, I talk to it almost exclusively in Portuguese.</p>

<p>Even when the repository is in English.</p>

<p>Even when the documentation is in English.</p>

<p>Even when the generated code must follow English naming conventions.</p>

<p>And this still feels a little amazing to me.</p>

<h2 id="talking-informally-to-the-agent">Talking informally to the agent</h2>

<p>The interesting part is not only the language itself.</p>

<p>The interesting part is how informal the interaction became.</p>

<p>When I am working on a feature, I usually talk to the AI agent in Portuguese, in a very natural way. I describe what I want, what I am worried about, what I think should be done first, and sometimes what I do not want it to do.</p>

<p>In many cases, before implementing the feature, the agent creates a Markdown document with the implementation steps.</p>

<p>That document is also written in Portuguese. 😀</p>

<p><a href="https://renanfranca.github.io/when-plan-mode-was-no-longer-enough.html">Later, I want to share more details about how I usually get that document created, because this small step has become an important part of my workflow.</a></p>

<p>But even with that planning document in Portuguese, the implementation itself remains aligned with the project.</p>

<p>Method names are in English.</p>

<p>Tests are in English.</p>

<p>Feature documentation is in English.</p>

<p>The code follows the repository language, not the language I used to describe my intention.</p>

<h2 id="the-repository-defines-the-language-of-the-work">The repository defines the language of the work</h2>

<p>After looking more carefully at what makes this possible, my conclusion is simple:</p>

<p>I provide the intention in Portuguese.</p>

<p>Codex reads the repository.</p>

<p>It sees that <a href="https://github.com/seed4j/seed4j-cli/blob/main/AGENTS.md"><code>AGENTS.md</code></a> is entirely in English.</p>

<p>It understands that the project is standardized in English.</p>

<p>Then it applies my request using the language of the project.</p>

<p>That means the agent is not just translating my words directly into files. It is reading the surrounding context and adapting the output to the conventions that already exist there.</p>

<p>This is the part that I find fascinating.</p>

<p>The conversation can happen in one language, while the work product follows another language.</p>

<p>The <a href="https://github.com/seed4j/seed4j-cli">seed4j-cli</a> is the project I am working on, where I have experienced everything I mentioned 😀</p>

<h2 id="intention-is-not-implementation">Intention is not implementation</h2>

<p>This made me think about the difference between intention and implementation.</p>

<p>When I talk to the agent in Portuguese, I am not asking it to make the project Portuguese.</p>

<p>I am using my native language to express intent with more precision, less friction, and more comfort.</p>

<p>The repository still has its own language.</p>

<p>The code still has its own conventions.</p>

<p>The documentation still has its own audience.</p>

<p>The agent becomes the bridge between those layers.</p>

<p>And maybe this is one of the reasons why working with AI agents feels different from only asking a chatbot to generate snippets. The agent is not only answering a question. It is operating inside a context.</p>

<h2 id="why-this-matters-to-me">Why this matters to me</h2>

<p>For a long time, I associated “better AI results” with “using English.”</p>

<p>That still may be true in many situations.</p>

<p>But with an agent working inside a repository, the situation becomes more nuanced.</p>

<p>The quality of the result does not depend only on the language of the prompt. It also depends on the quality of the repository context, the project conventions, the instructions, the tests, and the way the agent is asked to reason before changing code.</p>

<p>This is a very different experience.</p>

<p>I can think in Portuguese.</p>

<p>I can explain the intention in Portuguese.</p>

<p>I can ask questions in Portuguese.</p>

<p>But the final result can still respect an English-based open-source project.</p>

<p>That feels like a small but important shift in how I work.</p>

<h2 id="a-question-for-other-developers">A question for other developers</h2>

<p>I am still experimenting with this, but I am curious if other people are doing something similar.</p>

<p>Do you interact with an AI agent in a language other than English, even when the project itself uses English as its standard language?</p>

<p>And if you do, does the agent preserve the project language well?</p>

<p>I would love to hear how other developers are handling this.</p>]]></content><author><name>Renan Franca</name></author><category term="tales-of-a-dev" /><summary type="html"><![CDATA[How I started talking to Codex CLI in Portuguese while keeping open-source code, documentation, and project conventions in English.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://renanfranca.github.io/img/postbanners/2026-07-02-cover-intention-in-portuguese-code-in-english.jpg" /><media:content medium="image" url="https://renanfranca.github.io/img/postbanners/2026-07-02-cover-intention-in-portuguese-code-in-english.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Sharing Pieces of My AI Agent Workflow</title><link href="https://renanfranca.github.io/sharing-pieces-of-my-ai-agent-workflow.html" rel="alternate" type="text/html" title="Sharing Pieces of My AI Agent Workflow" /><published>2026-07-02T14:00:00+00:00</published><updated>2026-07-02T14:00:00+00:00</updated><id>https://renanfranca.github.io/sharing-pieces-of-my-ai-agent-workflow</id><content type="html" xml:base="https://renanfranca.github.io/sharing-pieces-of-my-ai-agent-workflow.html"><![CDATA[<p><img src="https://renanfranca.github.io/img/postbanners/2026-07-02-cover-sharing-pieces-of-my-ai-agent-workflow.jpg" alt="cover image" /></p>

<h2 id="why-i-stopped-writing-about-it">Why I stopped writing about it</h2>

<p>I had given up on writing about my progress with AI agents for a while.</p>

<p>Not because I stopped experimenting. Quite the opposite.</p>

<p>The problem is that everything changes too fast.</p>

<p>Every time I felt close to describing my workflow, I would improve something, replace a tool, change a prompt, adjust a habit, or discover a better way to interact with the agent. The idea of publishing a “complete workflow” started to feel wrong, because I knew it would become outdated almost immediately.</p>

<p>And I did not want to create an exhausting commitment for myself: writing a post today, then feeling forced to update it every time my process changed.</p>

<h2 id="why-i-did-not-want-to-sound-prescriptive">Why I did not want to sound prescriptive</h2>

<p>There was another reason too.</p>

<p>I did not want to sound like I was trying to impose a workflow.</p>

<p>My biggest discoveries with AI agents have been very individual. They did not come from a perfectly synchronized team process. They came from trial and error, from frustration, from curiosity, from small improvements, and from many moments where I had to rethink how I work as a software developer.</p>

<p>So, for some time, I preferred not to write about it.</p>

<h2 id="what-changed-my-mind">What changed my mind</h2>

<p>But recently, after watching the podcasts from <a href="https://stillburningpodcast.com/">Kent Beck - Still Burning</a>, I felt a strong desire to contribute more openly to this revolution that is happening.</p>

<p>AI agents are changing software development, but not only because of the tools themselves. They are also forcing us to rethink discipline, feedback loops, communication, design, testing, and the way we describe intent.</p>

<p>And I do not want to be only a consumer of this change.</p>

<p>I want to contribute to the conversation.</p>

<p>Maybe by sharing parts of what I am discovering, I can help someone else. And maybe, by making these ideas public, I can also accelerate my own learning through external insights, criticism, and suggestions.</p>

<h2 id="a-better-format">A better format</h2>

<p>So I started thinking about a better format.</p>

<p>Instead of trying to publish my entire workflow as if it were a recipe, I decided to share smaller steps from it.</p>

<ul>
  <li>Pieces.</li>
  <li>Practices.</li>
  <li>Decisions.</li>
</ul>

<p>Things that can be adapted, improved, questioned, or absorbed into someone else’s workflow.</p>

<p>That feels much more honest to me.</p>

<h2 id="what-i-want-to-share">What I want to share</h2>

<p>A complete AI agent workflow is too personal and too unstable to be treated as a final answer. But specific ideas can still be useful. A way to prepare context. A way to ask for changes. A way to review generated code. A way to avoid losing control. A way to keep tests and design as the center of the process instead of blindly trusting the agent.</p>

<p>That is what I want to share.</p>

<p>Not a definitive workflow.</p>

<p>Not a universal method.</p>

<p>Not “this is how everyone should work with AI agents.”</p>

<p>Just pieces of my current process, shared while they are still alive, still changing, and still being tested in real work.</p>

<p>I will start doing that soon.</p>]]></content><author><name>Renan Franca</name></author><category term="tales-of-a-dev" /><summary type="html"><![CDATA[Why I decided to share adaptable parts of my AI agent workflow instead of trying to publish a complete recipe.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://renanfranca.github.io/img/postbanners/2026-07-02-cover-sharing-pieces-of-my-ai-agent-workflow.jpg" /><media:content medium="image" url="https://renanfranca.github.io/img/postbanners/2026-07-02-cover-sharing-pieces-of-my-ai-agent-workflow.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Tales of a Dev - An Alternative Reality</title><link href="https://renanfranca.github.io/tales-of-a-dev-an-alternative-reality.html" rel="alternate" type="text/html" title="Tales of a Dev - An Alternative Reality" /><published>2026-03-05T13:30:00+00:00</published><updated>2026-03-05T13:30:00+00:00</updated><id>https://renanfranca.github.io/tales-of-a-dev-an-alternative-reality</id><content type="html" xml:base="https://renanfranca.github.io/tales-of-a-dev-an-alternative-reality.html"><![CDATA[<p><img src="https://renanfranca.github.io/img/postbanners/2026-03-05-cover-tales-of-a-dev-an-alternative-reality.jpg" alt="cover image" /></p>

<p>It’s been a little over a year since I realized that I work in the desert (<a href="https://martinfowler.com/bliki/ForestAndDesert.html">a term coined by Kent Beck</a>), and I understood why some things that are so useful and cool in the forest didn’t work when I tried to bring them into the desert.</p>

<h2 id="talking-to-people-outside-my-reality">Talking to people outside my reality</h2>

<p>So I decided to talk to people who are outside my reality to see how their day to day works, what new pain points they have that I’ll never experience in the desert because I’m dealing with more “basic” problems.</p>

<h2 id="learning-from-open-source-friends">Learning from open-source friends</h2>

<p>For a while now, I’ve been talking to people I work with on open-source projects (e.g., <a href="https://seed4j.com">seed4j.com</a>), and even though the project is incredible, it’s impossible to apply it in the desert where I work. I was fascinated to learn how they use it in their daily routine. It’s not just exciting because it’s something sophisticated; it’s genuinely useful and makes the day to day less stressful and overwhelming.</p>

<h2 id="replying-to-a-newsletter">Replying to a newsletter</h2>

<p>Recently, I received an email from a newsletter (I’ve subscribed to several), and what caught my attention was the frankness of the writing and a genuine invitation to reply because the author was interested in talking and getting insights from other people’s perspectives. I replied, and I’ve kept talking with him, someone who, in my opinion, works in the forest. These are interesting conversations that help me discover new things that my reality would hardly ever provide.</p>

<h2 id="catching-up-with-a-developer-friend">Catching up with a developer friend</h2>

<p>On top of that, I had the chance to talk over a video call with a developer friend I hadn’t spoken to in a long time. I was impressed to discover new areas where a developer can work, areas I didn’t even know existed. In the end, it felt like a conversation with a longtime friend. It had been a long time since I’d spoken English, but I felt so comfortable that at no point did I feel that speaking English was getting in the way.</p>

<h2 id="back-to-seed4j-cli">Back to Seed4J CLI</h2>

<p>I decided that I’m going to get back to working on the <a href="https://github.com/seed4j/seed4j-cli">Seed4J CLI</a>, but before that, I decided to reach out to other developers who use Seed4J to understand how they use it day to day and to learn a bit about their work routine. Surprisingly, a developer has already replied and supported me, saying that creating this CLI application might be a good path so that the AI can autonomously understand which features Seed4J has and use them whenever appropriate, making the experience more transparent.</p>

<h2 id="motivation-boost">Motivation boost</h2>

<p>This contact with other people in the software development industry, people living realities different from mine, gave me an extra boost of motivation. And the fact that everyone treated me with so much kindness and attention made me feel good.</p>]]></content><author><name>Renan Franca</name></author><category term="tales-of-a-dev" /><summary type="html"><![CDATA[It’s been a little over a year since I realized that I work in the desert (a term coined by Kent Beck).]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://renanfranca.github.io/img/postbanners/2026-03-05-cover-tales-of-a-dev-an-alternative-reality.jpg" /><media:content medium="image" url="https://renanfranca.github.io/img/postbanners/2026-03-05-cover-tales-of-a-dev-an-alternative-reality.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>